Inventory database design: schema, SQL template, ER diagram
A sound inventory management database design has three core tables and one rule. items holds
every SKU, locations holds every place stock can be, and stock_movements is an append-only
ledger with one signed row for each change in quantity. On-hand stock is never a column. It is
the sum of movements per item and location, exposed as a view. Purchase orders, goods receipts,
stocktakes and transfers get their own tables, and each of them writes to the ledger instead of
editing a number. A free SQL inventory database template
with example data is below, ready to run in PostgreSQL.
Inventory database schema: the tables at a glance
| Table | Key columns | Purpose |
|---|---|---|
items | sku (unique), name, unit, parent_item_id, reorder_point, is_active | One row per stockable SKU, variants included. No quantity column |
categories | name | Groups items for browsing and reporting |
item_attributes | item_id, name, value | Variant attributes such as size and colour |
item_units | item_id, unit, factor_to_base, barcode | Pack sizes such as a case of 12, converted to the base unit before anything reaches the ledger |
locations | code (unique), kind (store, stockroom, transit) | Every place stock can be, including goods on the road |
stock_movements | item_id, location_id, signed qty, reason, ref_type + ref_id, actor_id, occurred_at | The ledger: one append-only row per change in stock |
stock_on_hand (view) | item_id, location_id, qty | Current stock, derived as the sum of movements |
stock_balances (optional) | item_id, location_id, qty | A cache of the view, added only when the view is measurably too slow, and reconciled on a schedule |
purchase_orders + purchase_order_lines | number, supplier_id, status; item_id, qty_ordered, unit_cost_cents | What you ordered, as a state machine from draft to received |
goods_receipts + goods_receipt_lines | po_id (nullable), received_at; item_id, qty_received | What arrived, in as many deliveries as it took |
count_sessions + count_lines | status, scope; expected_qty snapshot, counted_qty | Stocktakes, with variance measured against a snapshot |
suppliers and users are referenced but not shown. Any standard shape works, as long as every
movement points at a real user.
Free SQL inventory database template and example
Download the PostgreSQL schema and sample transactions (.sql) · Download the ER diagram (.svg)
Run the SQL once in an empty practice database with PostgreSQL 16 or later:
psql -v ON_ERROR_STOP=1 -d your_practice_database -f inventory-ledger-example.sql
It creates a separate inventory_example schema, five tables, an on-hand view, immutable-ledger triggers and fictional stock movements. The final query returns 9 units in MAIN and 3 in TRANSIT for DEMO-001. Running it again stops at the existing schema rather than overwriting anything.
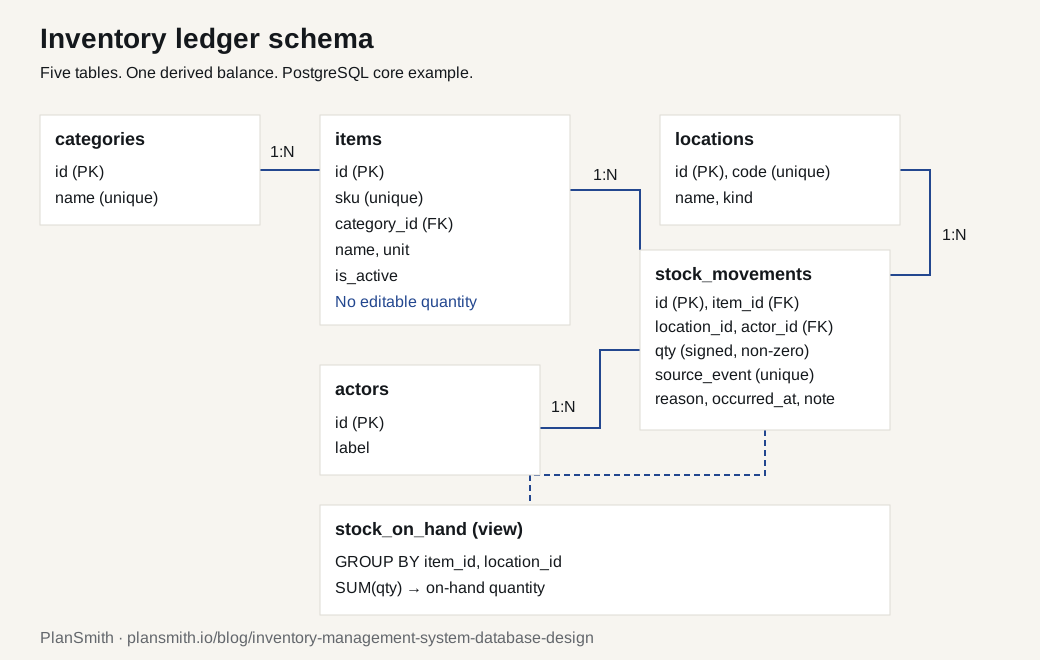
The runnable file covers the core ledger, not the entire application: categories, items,
locations, actors (standing in for users) and stock_movements, with a unique
source_event key in place of ref_type and ref_id so the same event cannot be posted twice. The
purchase-order, receipt, stocktake and variant snippets below explain additional design choices. Before production, add authentication and per-organisation authorization, decide whether negative stock is allowed, and enforce concurrent issue/transfer rules inside transactions. Append-only triggers prevent ordinary updates, deletes and truncation; database owners and superusers still control the schema and must not be your application role.
Database design for an inventory management system, step by step
- Write down the questions the system must answer. How much of each SKU is at each location now, and on a past date? Who changed it, and why? What is on order, in transit, or below its reorder point? Each is a query over movements, not a single editable number.
- List the entities, and split things from events. Things exist: items, locations, suppliers, users. Events happen to them: receipts, sales, counts, transfers, adjustments. Things become master tables. Events become rows that are never edited.
- Choose a ledger over a stored balance. On-hand is derived from movements. The next section explains why; it shapes every table after it.
- Close every set with constraints. Reasons and statuses become
checkconstraints or lookup tables, quantities get one sign convention, document lines get unique keys, and the ledger rejects updates and deletes with a trigger. The full list is in the constraints section below. - Index for the questions in step 1.
(item_id, location_id)serves on-hand and item history,occurred_atserves point-in-time and period reports, and(ref_type, ref_id)finds every movement a document caused. Add a cached balance table only when measurements say the view is too slow. - Test with a real sequence. Seed an opening balance, a receipt, a sale, a write-off and a transfer, then check the example queries against totals worked out by hand, as the downloadable file does.
Why the ledger comes first
The ER diagram most tutorials show for an inventory system is a products table with a quantity
column, a categories table beside it, and maybe suppliers and orders. It is also what a coding
agent produces if you ask for an inventory schema without saying more.
That schema is wrong in one specific place. products.quantity is a number somebody can type into.
The moment it exists, your database can no longer answer the question inventory software is really
asked: the shelf says nine and the system says twelve, so what happened?
On-hand stock is derived, never stored. Every change in quantity is an append-only row in a movement ledger, and the current level is the sum of those rows.
That single decision determines almost everything else in the design. It is also the capability that appears most often in the market: we maintain a hand-counted inventory of what retail stock systems ship, tallied across 120 retail-only sources, and on-hand stock derived by item and location (rather than held as an editable field) is evidenced in 32 of them, more than any other capability we counted. The movement ledger that makes it possible is named explicitly in 12.
The executable example and snippets use PostgreSQL. The ledger design can transfer to other databases, but trigger syntax, types and concurrency rules need a deliberate port.
The item master, and what it must not contain
create table items (
  id              bigserial primary key,
  sku             text        not null unique,
  name            text        not null,
  category_id     bigint      references categories(id),
  parent_item_id  bigint      references items(id),
  unit            text        not null default 'ea',
  cost_cents      integer,
  price_cents     integer,
  reorder_point   integer,
  is_active       boolean     not null default true,
  created_at      timestamptz not null default now()
);
There is no quantity column, and that omission is the entire design. Everything else is negotiable.
Two details worth arguing about while you are here. Store money as integer minor units
(cost_cents), not float: floating-point rounding in a stock valuation report is a bug you will
find during an audit rather than during development. And prefer is_active over deleting items. A
deleted SKU orphans every historical movement that referenced it, and you will want those
movements in three years when somebody asks about a supplier dispute.
Product inventory: variants, SKUs and units of measure
A product and a SKU are not the same thing. The product is what a customer browses, such as an
Oxford shirt. The SKU is what you count on a shelf: the Oxford shirt in navy, size M. Stock lives at
the SKU level, so the honest version is that a variant is an item. Give it its own row and its own
SKU, with parent_item_id pointing at a style row that carries the shared name and category and
never receives movements. A separate variants table with its own quantity column reintroduces the
bug you just removed, one level down.
create table item_attributes (
  item_id  bigint not null references items(id),
  name     text   not null,  -- 'size', 'colour'
  value    text   not null,  -- 'M', 'navy'
  primary key (item_id, name)
);

create table item_units (
  item_id         bigint  not null references items(id),
  unit            text    not null,  -- 'case'
  factor_to_base  integer not null check (factor_to_base > 0),  -- 12
  barcode         text    unique,
  primary key (item_id, unit)
);
Size and colour go in item_attributes, one row per attribute, so adding material or fit later
needs no migration.
Units of measure follow one rule: the ledger stores base units only. items.unit is the unit
you count in (each, gram, metre). A supplier that ships cases of 12 gets an item_units row with
factor_to_base = 12, and receiving 5 cases writes one movement of 60. Let a case into qty and the
on-hand view starts adding cases to eaches. The barcode sits on the unit row because a case and a single item usually carry
different barcodes, and scanning either should resolve to the same item. If you sell by weight or
length, pick a small base unit such as grams or millimetres so qty stays an integer, or change
qty to numeric everywhere at once.
Locations
create table locations (
  id    bigserial primary key,
  code  text not null unique,
  name  text not null,
  kind  text not null default 'store'
        check (kind in ('store', 'stockroom', 'transit'))
);
Add this on day one even if you have exactly one shop. Retrofitting a location dimension means rewriting every balance query and backfilling every historical row, and single-location systems grow a second location far more often than they get rewritten.
The transit kind matters later. See transfers.
The movement ledger
This is the table the tutorials leave out.
create table stock_movements (
  id           bigserial   primary key,
  item_id      bigint      not null references items(id),
  location_id  bigint      not null references locations(id),
  qty          integer     not null check (qty <> 0),
  reason       text        not null
               check (reason in ('opening','receipt','sale','adjustment',
                                 'count','transfer','return','damage','shrinkage')),
  ref_type     text,
  ref_id       bigint,
  note         text,
  actor_id     bigint      not null references users(id),
  occurred_at  timestamptz not null default now()
);

create index on stock_movements (item_id, location_id);
create index on stock_movements (occurred_at);
create index on stock_movements (ref_type, ref_id);
Signed quantities: positive for stock in, negative for stock out. check (qty <> 0) because a
zero-quantity movement is always a bug and it is cheaper to reject it than to explain it.
reason is constrained rather than free text: the day someone asks "how much did we lose to damage
last quarter" you need damage to mean one thing. A lookup table works equally well. The point is
that the set is closed.
ref_type and ref_id are the loose pointer back to whatever caused the movement: a receipt, a
count session, a transfer. A polymorphic reference is not beautiful, but the alternative is nine
nullable foreign-key columns, and this table is going to be your largest.
actor_id is not optional. A movement without an actor is an anonymous change to your stock
figure, which is precisely the thing you built the ledger to prevent.
Making it immutable in the database
A ledger you can UPDATE is not a ledger, it is a table with good intentions. Enforce it in the
database, not in the application layer, because the application layer is where the admin screen
lives and the admin screen is what will edit it:
create function stock_movements_append_only() returns trigger
language plpgsql as $$
begin
  raise exception 'stock_movements is append-only (attempted %)', tg_op;
end $$;

create trigger stock_movements_immutable
  before update or delete on stock_movements
  for each row execute function stock_movements_append_only();
Corrections are new rows with the opposite sign and a reason, exactly as an accounting system reverses an entry. Never an edit. This is the constraint that survives a change of developer.
On-hand
create view stock_on_hand as
select item_id, location_id, sum(qty)::int as qty
from stock_movements
group by item_id, location_id;
That view is your stock level. Every screen, every report and every reorder rule reads it.
It is fast enough for longer than people expect: a few million movement rows aggregate comfortably with the index above. When it is not, the answer is a cache you can prove right:
create table stock_balances (
  item_id      bigint not null references items(id),
  location_id  bigint not null references locations(id),
  qty          integer not null,
  primary key (item_id, location_id)
);
Update it from a trigger on insert into stock_movements, and keep this query as a scheduled
reconciliation:
select b.item_id, b.location_id, b.qty as cached, v.qty as ledger
from stock_balances b
full join stock_on_hand v using (item_id, location_id)
where b.qty is distinct from v.qty;
If that returns rows, the cache is wrong and the ledger is right. Always. Do not add the cache before you need it, and never let the cache become the source of truth. That is the original bug wearing a hat.
Purchase orders, which are a state machine
Where most schemas go wrong the second time is treating a purchase order as a document rather than a process. In the market inventory we counted, the full PO lifecycle (draft through sent, partial receipt, and close) is evidenced in 24 of 120 sources, joint second only to the item master itself. Receiving against those POs is evidenced in 18.
create table purchase_orders (
  id           bigserial   primary key,
  number       text        not null unique,
  supplier_id  bigint      not null references suppliers(id),
  location_id  bigint      not null references locations(id),
  status       text        not null default 'draft'
               check (status in ('draft','sent','partially_received',
                                 'received','cancelled')),
  ordered_at   timestamptz,
  closed_at    timestamptz,
  created_by   bigint      not null references users(id)
);

create table purchase_order_lines (
  id               bigserial primary key,
  po_id            bigint    not null references purchase_orders(id) on delete cascade,
  item_id          bigint    not null references items(id),
  qty_ordered      integer   not null check (qty_ordered > 0),
  unit_cost_cents  integer   not null,
  unique (po_id, item_id)
);
Note what is not on purchase_order_lines: a qty_received column. It is the quantity bug
again in a different table. Deliveries arrive in parts, short, substituted and occasionally twice,
and a single mutable counter cannot represent any of that.
Receipts are their own events:
create table goods_receipts (
  id           bigserial   primary key,
  po_id        bigint      references purchase_orders(id),
  location_id  bigint      not null references locations(id),
  received_at  timestamptz not null default now(),
  actor_id     bigint      not null references users(id),
  note         text
);

create table goods_receipt_lines (
  id            bigserial primary key,
  receipt_id    bigint    not null references goods_receipts(id) on delete cascade,
  po_line_id    bigint    references purchase_order_lines(id),
  item_id       bigint    not null references items(id),
  qty_received  integer   not null check (qty_received > 0)
);
Received-to-date is a sum over goods_receipt_lines, the same way on-hand is a sum over movements.
po_id is nullable because ad-hoc receiving, a delivery nobody raised an order for, is a real
event in every shop, and a schema that cannot record it forces someone to invent a fake PO.
Committing a receipt writes one stock_movements row per line, with reason = 'receipt' and
ref_type = 'goods_receipt'. The PO status is recalculated from the sums, not set by hand.
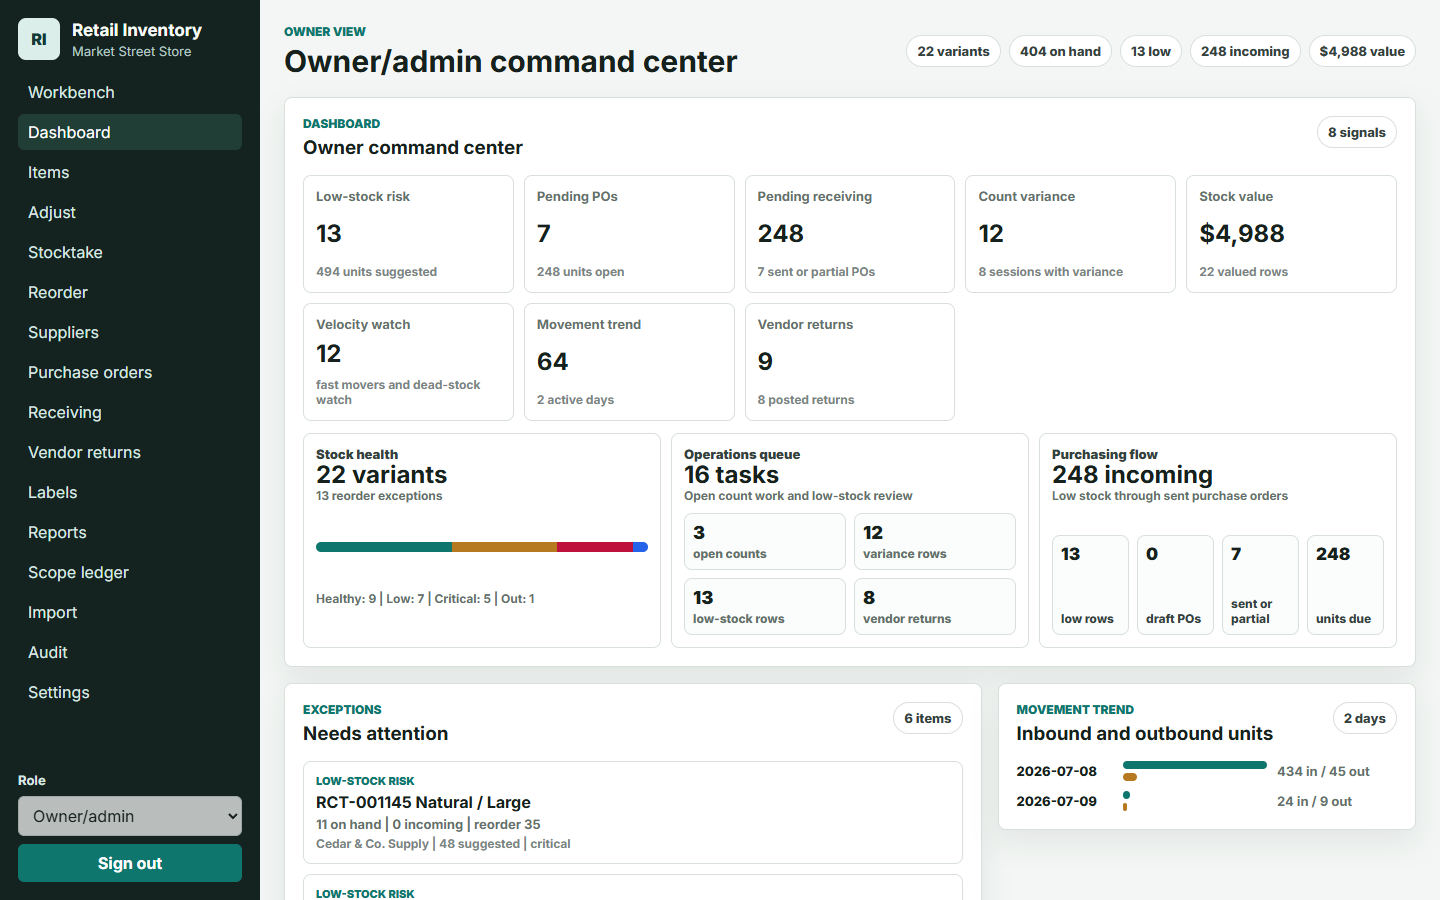 The stock clerk screen of Northline Outfitters, an inventory app GPT-5.5 built from the Retail Inventory planner. The right column lists open purchase orders waiting to be received. Open the live demo.
Stocktakes, which are a session
A stocktake is not a form that overwrites quantities. It is a session with a lifecycle, and it is evidenced in 23 of the 120 sources we counted.
create table count_sessions (
  id            bigserial   primary key,
  location_id   bigint      not null references locations(id),
  status        text        not null default 'open'
                check (status in ('open','review','committed','cancelled')),
  scope         text        not null default 'full'
                check (scope in ('full','cycle')),
  opened_at     timestamptz not null default now(),
  committed_at  timestamptz,
  actor_id      bigint      not null references users(id)
);

create table count_lines (
  id            bigserial primary key,
  session_id    bigint    not null references count_sessions(id) on delete cascade,
  item_id       bigint    not null references items(id),
  expected_qty  integer   not null,
  counted_qty   integer,
  unique (session_id, item_id)
);
expected_qty is a snapshot taken when the session opens, and it is the detail almost every
implementation misses. Variance has to be measured against what the system believed at the moment
counting began. If you compute it live, a sale rung up while somebody is walking the stockroom
changes the variance under their feet, and the count stops meaning anything.
Committing the session writes one movement per non-zero variance with reason = 'count' and a
reference to the session, then sets status = 'committed'. After that the session is read-only;
enforce it with the same trigger pattern as the ledger. That lock is what makes a stocktake
auditable rather than decorative.
Transfers, and where stock lives while it is on a van
The naive design is a transfers table with a status column and a pair of adjustments at either
end. It leaves stock existing nowhere in between, so your total stock value drops for two days and
nobody can say why.
Use the transit location instead. A dispatch is two movements: out of the source, into transit.
A receipt at the far end is two more: out of transit, into the destination.
-- dispatch 10 units from MAIN
insert into stock_movements (item_id, location_id, qty, reason, ref_type, ref_id, actor_id)
values (:item, :main, -10, 'transfer', 'transfer', :transfer_id, :actor),
       (:item, :transit, 10, 'transfer', 'transfer', :transfer_id, :actor);
The ledger stays balanced, stock in transit is a query rather than a special case, and a shortfall on arrival is visible as a residual balance in the transit location instead of vanishing. Transfers appear in 15 of the 120 sources: common, and optional for a first version.
The constraints that are load-bearing
- No table other than
stock_movementsmay write a quantity. If you enforce one thing at review time, enforce this. - Every status column is a
checkconstraint or a lookup table. Free-text status is how you end up withsent,SentandSENTin the same column. - Every quantity has a sign convention written down, and it is the same everywhere. So is its unit: base units only.
unique (session_id, item_id)on count lines, andunique (po_id, item_id)on PO lines. Both stop the duplicate-row class of bug that produces double-counted stock.- Foreign keys are real foreign keys, not application-level conventions. An orphaned movement is unresolvable after the fact.
Example queries
Every query reads the ledger or the view, never a stored quantity. The first and third run
unchanged against the downloadable file once you point your session at its schema with
SET search_path = inventory_example; (the file's own setting ends when its transaction commits).
The low-stock query uses reorder_point from the item master above, which the download leaves out.
Stock on hand per location:
select l.code as location, i.sku, i.name, s.qty
from stock_on_hand s
join items i on i.id = s.item_id
join locations l on l.id = s.location_id
where s.qty <> 0
order by l.code, i.sku;
Items at or below their reorder point, counting sellable stock only:
select i.sku, i.name, i.reorder_point,
       coalesce(sum(s.qty) filter (where l.kind <> 'transit'), 0) as on_hand
from items i
left join stock_on_hand s on s.item_id = i.id
left join locations l on l.id = s.location_id
where i.is_active and i.reorder_point is not null
group by i.id
having coalesce(sum(s.qty) filter (where l.kind <> 'transit'), 0) <= i.reorder_point
order by on_hand, i.sku;
The left joins keep items that have never had a movement, so a new SKU with a reorder point shows as zero instead of disappearing. Stock in transit is excluded because nobody can sell it yet.
Movement history for one SKU, with a running balance:
select m.occurred_at, l.code as location, m.reason, m.qty,
       sum(m.qty) over (partition by m.location_id
                        order by m.occurred_at, m.id) as running_qty
from stock_movements m
join items i on i.id = m.item_id
join locations l on l.id = m.location_id
where i.sku = 'DEMO-001'
order by l.code, m.occurred_at, m.id;
This is the query that answers "the shelf says nine and the system says twelve". For stock on a
past date, run the on-hand aggregate with where occurred_at < '2026-10-01'. A schema with a
stored quantity column cannot answer either question.
Migrating a schema that already has products.quantity
The path is not hard; the last step is the one people skip.
- Create
stock_movementsandlocations. Nothing reads them yet. - Backfill one opening movement per item:
reason = 'opening', quantity equal to the current value, dated to now, actor set to the migration. You are not recovering history you never had; you are establishing a floor from which history begins. - Add the
stock_on_handview. Confirm it matches the old column exactly for every item. Any mismatch here is a backfill bug, not a rounding issue. - Route every write through the ledger. Receiving, adjustments, counts, sales. This is the bulk of the work and it is where you will find the three code paths nobody remembered.
- Switch reads to the view.
- Drop
products.quantity. Do it. While the column exists, something will write to it (a report, an import script, an admin screen, a well-meaning new developer) and you will be back where you started with the added confusion of two disagreeing numbers.
Between steps 5 and 6, run the reconciliation query above on a schedule. It is the cheapest bug detector you will ever write.
Why coding agents get this wrong
Ask an agent for an inventory database and it produces the tutorial schema, because that is what the training data is full of. It is a specification failure, not a reasoning failure: nothing in "build an inventory management system" says on-hand must be derived.
We have watched this directly. Eight working retail stock systems were built from a single planner by four different coding models, and the pattern in the audits was consistent: the visible features arrived, and the substrate was where the differences were. Two of the eight stored everything in flat files rather than a database at all. One could not be served as a single application in production. One shipped with no sign-in whatsoever, and another let you pick a user from a list. The build that scored highest on data integrity was the one whose on-hand figure could only move through a receipt, an adjustment, a count or a return, each recorded with the before and after values and the person responsible.
That is the whole difference, and it is a schema decision made before the first line of application code.
Common questions
What tables does an inventory database need?
At minimum items, locations and stock_movements, plus a stock_on_hand view that sums the
movements. Most systems then add categories, suppliers, users, purchase orders, goods receipts
and stocktake sessions. The schema table lists
the key columns of each.
Is there a free SQL inventory database template I can use?
Yes. The downloadable .sql file is an inventory database
example for PostgreSQL 16 or later that you may use and adapt. It creates five tables, the on-hand
view, append-only triggers and sample movements in its own inventory_example schema. It covers
the core ledger only, so purchase orders, stocktakes, sign-in and permissions are yours to add.
Is stock management database design different from inventory database design?
No. "Stock" and "inventory" name the same thing, and the design is the same: one row per change in quantity, and current stock derived from those rows. Some teams say stock for a shop floor and inventory for a warehouse, but the tables do not change.
Should the products table have a quantity column?
No. A stored quantity can be typed over, and then nothing explains why the shelf and the system disagree. Keep quantity in the movement ledger and read it from the on-hand view. If the view gets slow, add a cached balance table that is reconciled against the ledger on a schedule.
If you want the sequence rather than the schema, how to build a retail inventory management system covers the build order and why it matters. What a retail inventory management system includes is the full counted feature inventory these figures come from, and inventory management in Excel is the same ledger rule expressed as three spreadsheet tabs, if you are not ready for a database yet.
The same approach, applied to other systems: ecommerce database design, POS database design, fleet management database design and school management system database design.
And if you are pointing a coding agent at this, the Retail Inventory Management planner is the spec we hand ours: the ledger rule, the lifecycle states and the scope boundaries written so the agent has to build them rather than skip to the tutorial schema.